unsloth
LLM fine-tuning acceleration library — claims 2–5× faster training and 70% less VRAM
An LLM fine-tuning acceleration library claiming 2–5× speedups and 70% less VRAM; a staple for local fine-tuning.
Run open LLMs on your own machine — no API bills, no data leaving your device.
Key features
- Desktop app to run and train LLMs, diffusion, TTS, embedding models
- Fine-tuning runs 2x faster with 70% less VRAM, no accuracy loss
- Supports LoRA, QLoRA, full fine-tuning, GRPO, DPO, RL, FP8
- Exports GGUF, NVFP4, FP8 and serves an OpenAI-compatible API
- One command connects Claude Code or Codex to local models
Good for
- Fine-tuning open models on consumer-grade GPUs
- Running local LLMs with coding agents and MCP tools
Stack & tags
fine-tuningllm-traininglorarlopen-weightsdesktop-applocal-inference
Quick start
curl -fsSL https://unsloth.ai/install.sh | shFrom the project README on GitHub.
Screenshots
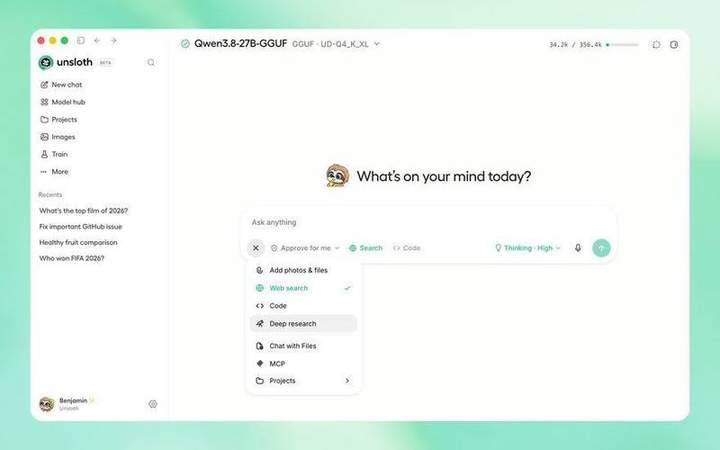
Screenshots from the project’s GitHub README.