llama.cpp
C/C++ LLM inference engine, birthplace of the GGUF format; powers Ollama under the hood
A C/C++ LLM inference engine and the origin of the GGUF quantization format. It powers Ollama under the hood and runs on pure CPU.
Run open LLMs on your own machine — no API bills, no data leaving your device.
Key features
- LLM and VLM inference in plain C/C++ with no dependencies
- Optimized for Apple Silicon, x86 AVX, CUDA, HIP, Vulkan, and SYCL backends
- 1.5-bit to 8-bit integer quantization for faster inference and less memory
- CPU+GPU hybrid inference for models larger than total VRAM
- Ships llama cli and an OpenAI-compatible API server
Good for
- Running large language models efficiently on local hardware
- Embedding fast inference into C/C++ applications
Stack & tags
CC++llm-inferencecppquantizationgpulocal-inferenceopen-modelsggml
Quick start
llama cli -hf ggml-org/Qwen3.5-0.8B-GGUFFrom the project README on GitHub.
Screenshots
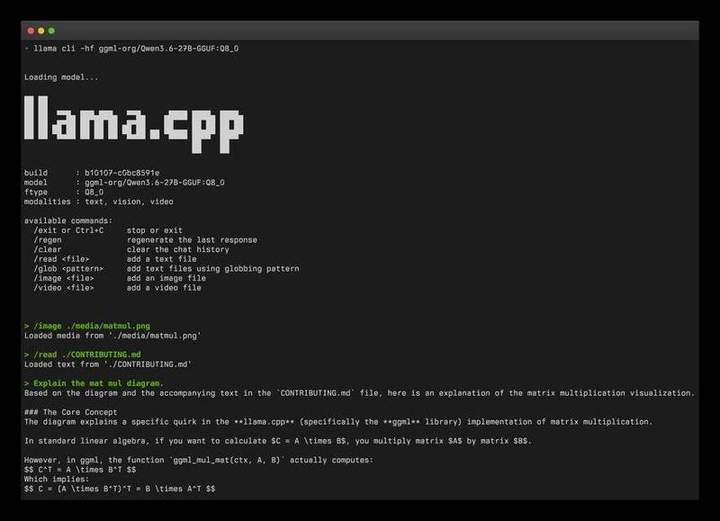
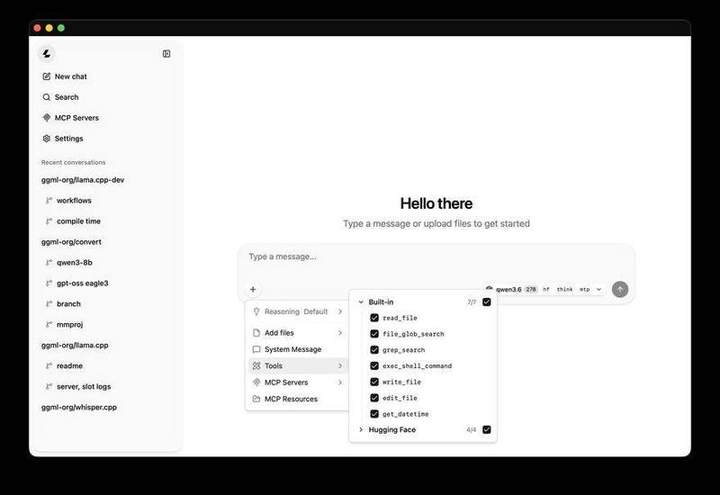
Screenshots from the project’s GitHub README.