PaddleOCR
Baidu Paddle's OCR toolkit — superb Chinese recognition for document digitization
Baidu Paddle's OCR toolkit with superb Chinese recognition; an essential for document digitization.
Search engines, scrapers, and data infrastructure for AI pipelines.
Key features
- Converts PDFs and images into structured LLM-ready JSON/Markdown
- 100+ language text recognition with PP-OCRv6 unified model
- Document VLM PaddleOCR-VL-1.6 for formula, table and chart parsing
- One-click deployment on GPU, CPU, XPU and AI accelerators
Good for
- RAG and agentic apps needing OCR as a data foundation
- Edge and cloud document parsing with small-footprint models
Stack & tags
ocrdocument-aipdf-parsingvlmmultilingualragopen-source
Screenshots
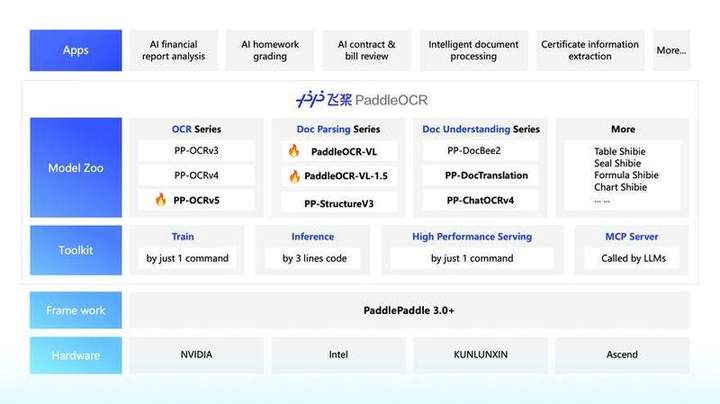
Screenshots from the project’s GitHub README.